The AI competition of 2026 has shifted from choosing a smarter model to designing a more reliable operating system. Performance is now the starting point; operations determine the outcome.
A clear change is visible in the field. Where the key question used to be ‘Which model is smartest?’, the more important question now is ‘How does our team recover when this model fails?’ Even with the same model, some teams produce consistent results while others fluctuate every time. The difference comes from operational design, rather than model intelligence.
Giving every role to a single agent looks fast at first. One prompt, one response, one result. But the drawbacks emerge as operations continue. Input quality validation, external API exception handling, and control over the final prose are bundled together, making it difficult to isolate the cause of a failure. Problems recur, and the team is left with emotionally charged retrospectives asking, ‘Why did quality drop again today?’
 A beautiful abstract scene reminiscent of an agent collaboration dashboardView original
A Team with Separate Roles Is Stronger Than a Single Genius
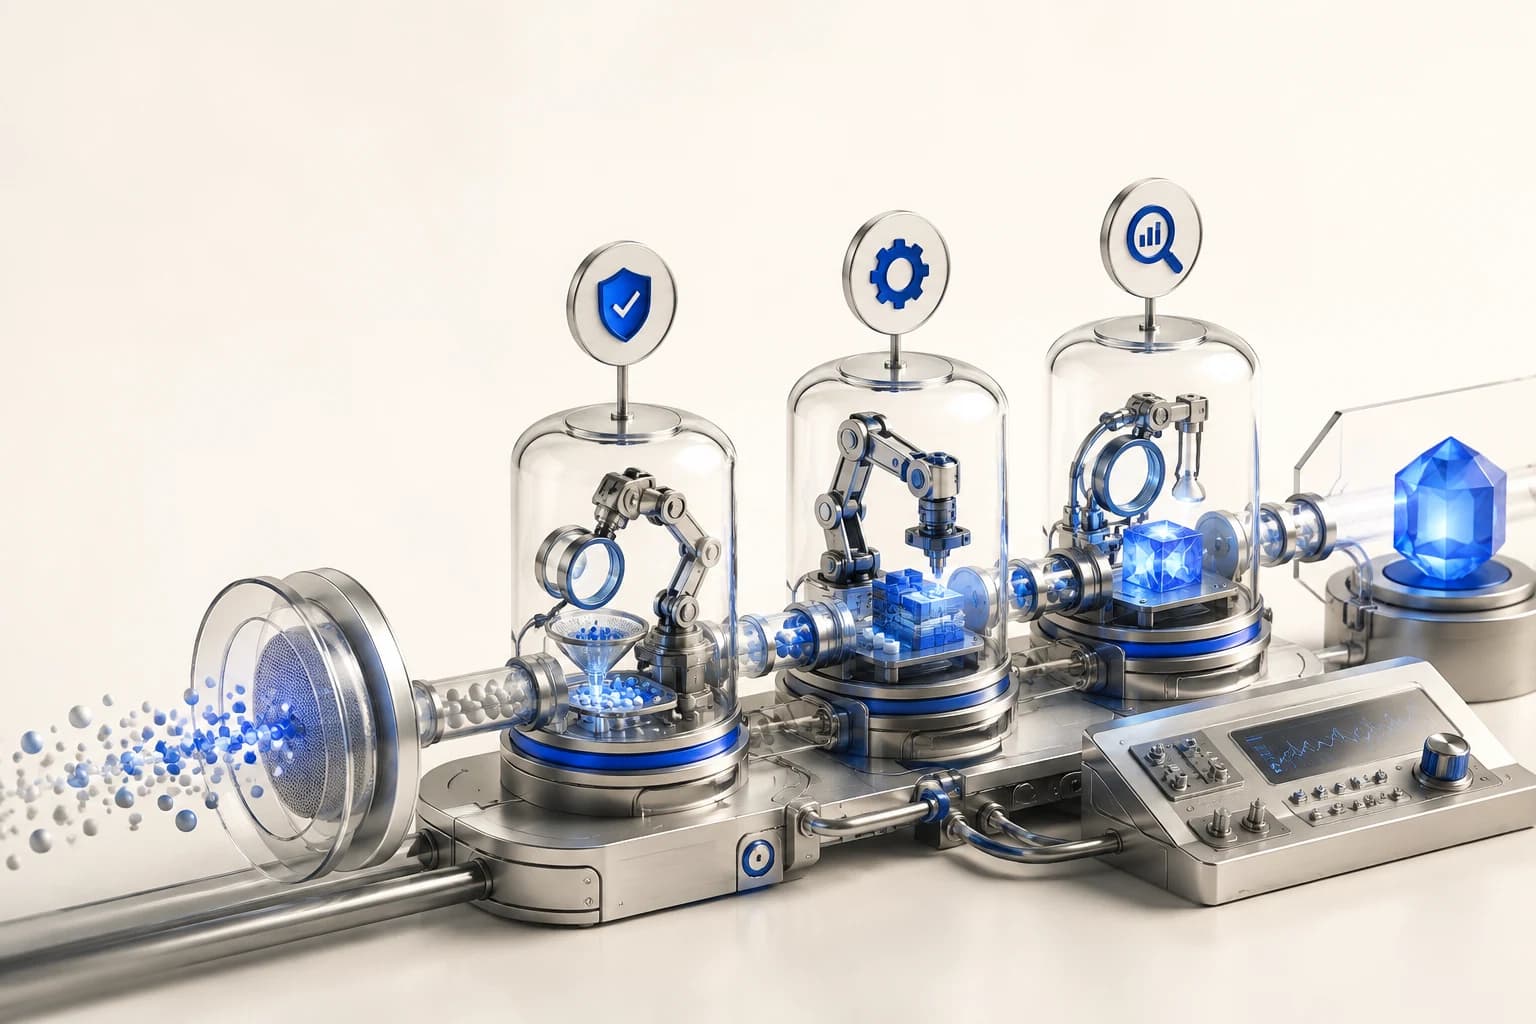
Organizations that deliver results consistently divide roles. They separate responsibilities into agents for input validation, execution, and quality monitoring, with clear output criteria for each stage. This approach may look a little cumbersome, but it has an overwhelming practical advantage: failure points appear in logs, the scope of fixes narrows, and improvements become reproducible.
The key here is controlling variability rather than maximizing performance. A reliable average matters more to a business than an occasional perfect score. In fields with many repetitive tasks, such as content automation, customer support, and operational reporting, ‘100 reliable runs’ create far greater value than ‘one spectacular success.’ A team-based agent structure is specifically suited to raising this average quality.
Another important criterion is permission boundaries. It is safer to separate read operations from write operations and put external publishing behind a separate approval gate. In automated publishing pipelines in particular, successful image generation must be enforced as a quality gate. A rule against publishing when visual quality falls below the standard is not an obstacle that slows things down; it is a firewall that protects brand trust.
 A layered abstract structure symbolizing permission boundaries and quality gatesView original
Reduce Costs through Stage Design, Not Model Tiers
Many teams understand cost optimization only as ‘switching to a cheaper model.’ In practice, however, stage design determines cost. If a low-cost model drafts, a mid-tier model validates structure, and a high-performance model polishes the final prose, the overall quality can be maintained while cost variability falls. Conversely, running every stage through a single top-priced model lengthens revision loops and lets total cost balloon easily.
Observability is essential too. Without recording which inputs repeatedly fail and which prompt patterns improve quality, improvement depends on intuition. Recording the request ID, stage name, input summary, and output evaluation in a standard schema shifts team retrospectives from ‘feelings’ to ‘evidence.’ As this shift accumulates, improvement accelerates and dependence on individual ability decreases.
Organizational culture has already begun to change as well. As the boundaries between writer, editor, and publisher blur, system designers and operations curators become more valuable. Ultimately, teams that use AI well are those that connect things safely and consistently, rather than simply generate more.
 An agent operations ecosystem connected like neon data flows through a cityView original
The Next Competition Is about Delivering the Right Answer, Not Just Generating It
The competitive landscape over the next 12 months will become clearer. Teams that make different agents collaborate safely will outlast those clinging to the smartest model alone. Organizations that win in the market do not merely create a good answer once; they reliably deliver answers every day.
Implementation does not need to be grand. Adding just three things to your existing pipeline can make a noticeable difference.
- Separate roles by stage (input validation / execution / quality monitoring)
- Quality gates before external publishing (especially image and expression standards)
- Standardized logs per request (to make failures reproducible)
AI operations are no longer a laboratory topic. They have already become basic work infrastructure. What is needed now, then, is operational design that reduces failures and protects trust, rather than a more dazzling demo. Performance shines over a short distance; operations win over the long distance. And teams that win over the long distance ultimately become the market standard.