When agents take over the front end of work, teams become noticeably faster. Incoming requests are classified, drafts prepared, and necessary tool calls linked automatically. On the surface, operations look much smoother. After a while, however, most teams hit a similar wall: too much time begins leaking through failures rather than successes. Normal flows accelerate while exception flows become slower. As the gap widens, users trust the system less and operators feel more anxious as automation increases.
Operational quality can therefore no longer be explained by accuracy, cost, and response speed alone. A key additional metric in the agent era is escalation latency. Unless teams shorten the time between detecting a problem and human intervention that stabilizes it, even small errors erode organizational trust. Manage that interval systematically, however, and services can operate stably even without perfect model performance.
1. Automation’s real bottleneck appears at the transfer of responsibility, not inference
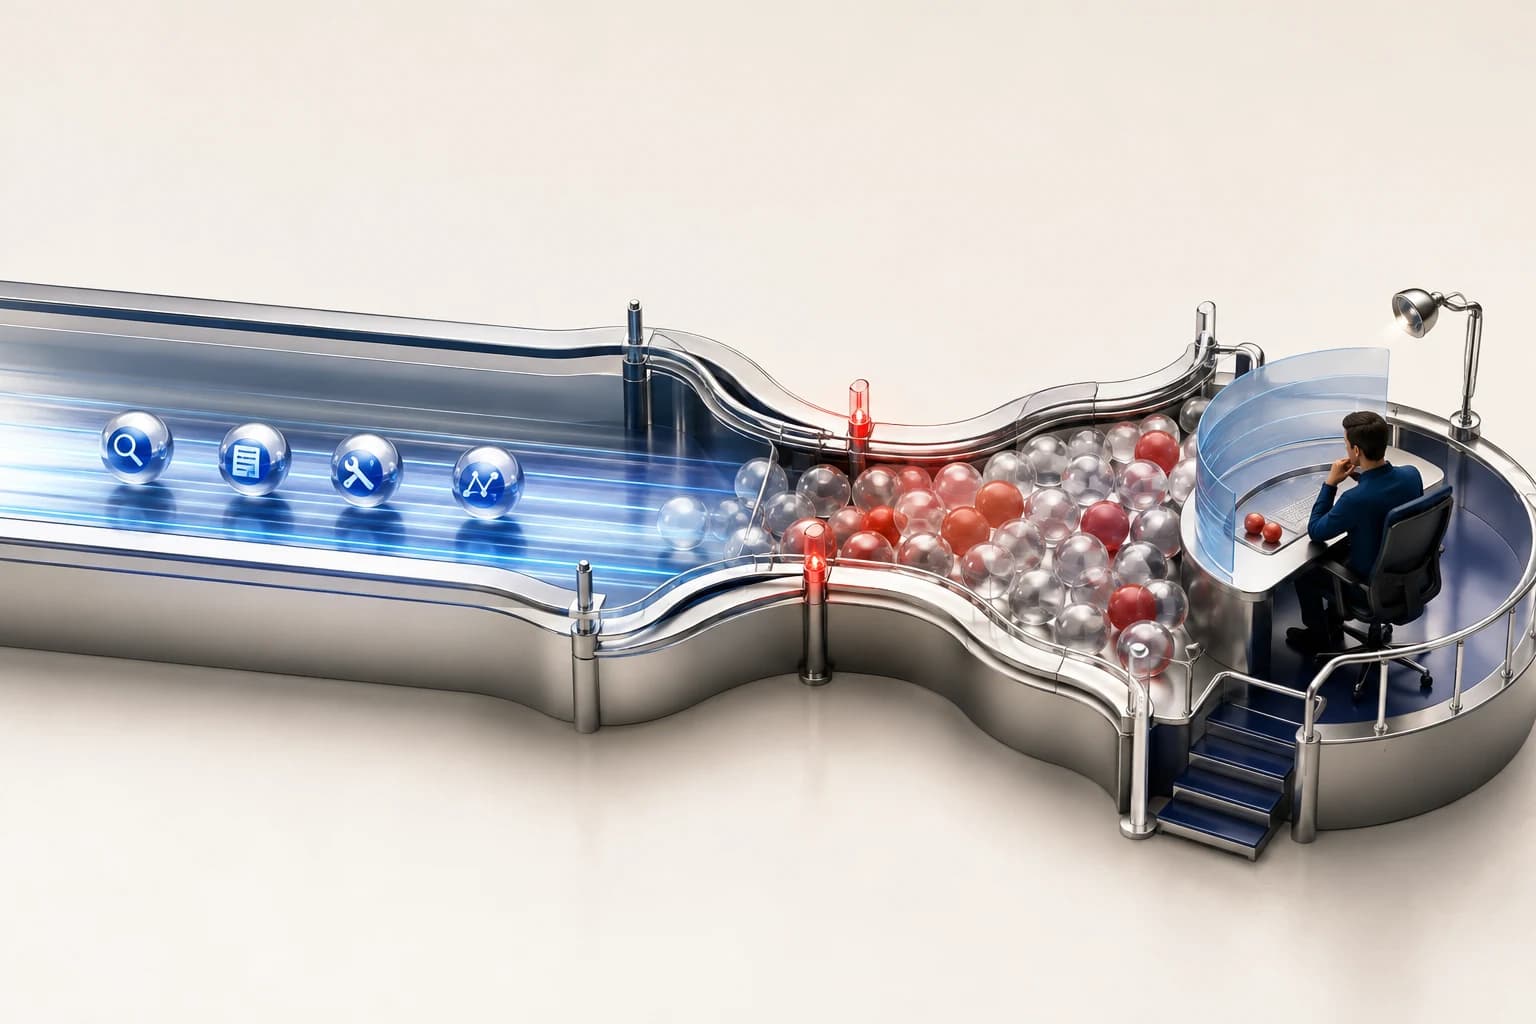
 An operational flow diagram showing accumulating escalation latencyView original
A familiar scene occurs in operations. An agent receives an ambiguous request and determines that internal rules require human review. So far, it has worked well. The problem follows: the recipient is unclear, supporting evidence is not organized, and half the context has disappeared by the time someone checks. The recipient searches raw logs, gathers related history, and reconstructs why work stopped. Technically, escalation happened; operationally, it is little different from a halt.
Many teams mistake this for a performance problem: “A smarter model would not have handed it over.” That is partly true. In reality, though, more delay comes from a weak interface for transferring responsibility. Explaining failure matters as much as reducing it. Human intervention cannot accelerate unless one screen conveys the stop signal, the triggered policy clause, alternative paths, and the level of impact users feel.
Conflicting priorities create another bottleneck. Several warnings arrive simultaneously: payment issues, publishing failures, personal-information masking alerts, and external API delays. Without clear severity criteria, the recipient handles the loudest alarm first—the most visible issue rather than the most important. More sophisticated automation creates more warnings, so without a priority system the team inevitably falls into a war of attrition.
The conclusion is simple. Escalation is not a feature ending at “handed over,” but operational design extending to “delivered so it can be handled immediately.” Without this perspective, faster automation loses trust faster.
2. Manage the trust budget through recovery rhythm, not failure count
 A tracking board showing trust budgets and recovery rhythms over timeView original
Users do not expect a system never to be wrong. They are more sensitive to its behavior afterward. Quickly acknowledging a problem, explaining its scope, giving a recovery estimate, and showing recurrence-prevention measures preserve trust. Conversely, early silence or confusion sharply reduces trust even if the precise cause is eventually found. Operations teams should measure recovery rhythm as carefully as failure rate.
In practice, managing a trust budget in four stages works well. First, detection time: from anomaly onset to discovery. Second, classification time: time to grade the detected issue by severity and impact. Third, intervention time: until the responsible person actually executes a fix or mitigation. Fourth, explanation time: until the current state is shared with users or internal stakeholders. If any of these intervals grows long, perceived trust drops rapidly.
Do not set excessive targets. Promising an immediate response in every case quickly burns the team out. Define service levels by grade instead: initial intervention within ten minutes for high-risk issues, within thirty for medium risk, and during the next deployment window for low risk. Consistency is central. Users trust predictability more than perfection. Repeated patterns explaining how each problem type is handled within a known time sustain trust in the automation system.
The trust budget must also be viewed in terms of depletion and replenishment. Consecutive incidents consume it quickly; clear recovery communication restores it. Tracking this numerically makes the team’s state intuitive to read. It is far more practical than a simple error count. Trust may look emotional, but translated into operational language it becomes a manageable asset.
3. Three mechanisms for reducing escalation latency: packets, slots, and reviews
 An operating protocol map showing the packet-slot-review loopView original
The first mechanism is a standardized escalation packet. Bundle the minimum information required for human intervention into a fixed format: original request, policy trigger, failure point, recommended action, user impact, and rollback availability. With a standard format, recipients no longer need to reconstruct logs like detectives every time. Intervention quality rises and average handling time falls.
The second is on-call slot design. “Someone will see it” creates the most expensive delay. Specify primary responders, backups, and approvers for each time period to reduce responsibility gaps. Nights and weekends become especially important as automation grows. Agents run twenty-four hours a day, but human attention does not. Slots preserve system trust by acknowledging human limits.
The third mechanism is a short review loop. Waiting for a long, heavy retrospective after an incident delays improvement. First run an immediate fifteen-minute review, recording cause, response, and next action on one page. Add structural improvements in the weekly review afterward. Immediate reviews increase learning speed; weekly reviews deepen recurrence prevention. Either one alone produces only half the effect.
Together, these mechanisms create a clear change. When alarms sound, nobody wonders who should do what first. Evidence behind responses accumulates, and operational metrics improve alongside the quality users feel. Automation maturity ultimately appears less in how much was automated than in how calmly recovery proceeds when trouble comes.
An agent team’s advantage comes not from the peak of an accuracy graph, but from a rhythm that withstands disturbance without collapsing. Today’s task is simple. Replace a vague determination to prevent the next incident with a design that can move without delay when it arrives. That is the most realistic way to protect a trust budget.