Automation usually fails not because technology is lacking, but because there is no agreement on who may decide what, or who restores what within how much time after failure.
When teams begin expanding their work with agents, the initial effect is clear. Repetitive tasks become faster and people less exhausted. The problem begins afterward. As success stories accumulate, teams naturally hand more authority to models. They delegate classification as well as summaries, proposal drafts as well as classification, and eventually want to delegate decisions just before external delivery. The productivity graph climbs steeply, but the risk curve rises with it. Most organizations first ask at this point: “How far may we automate?”
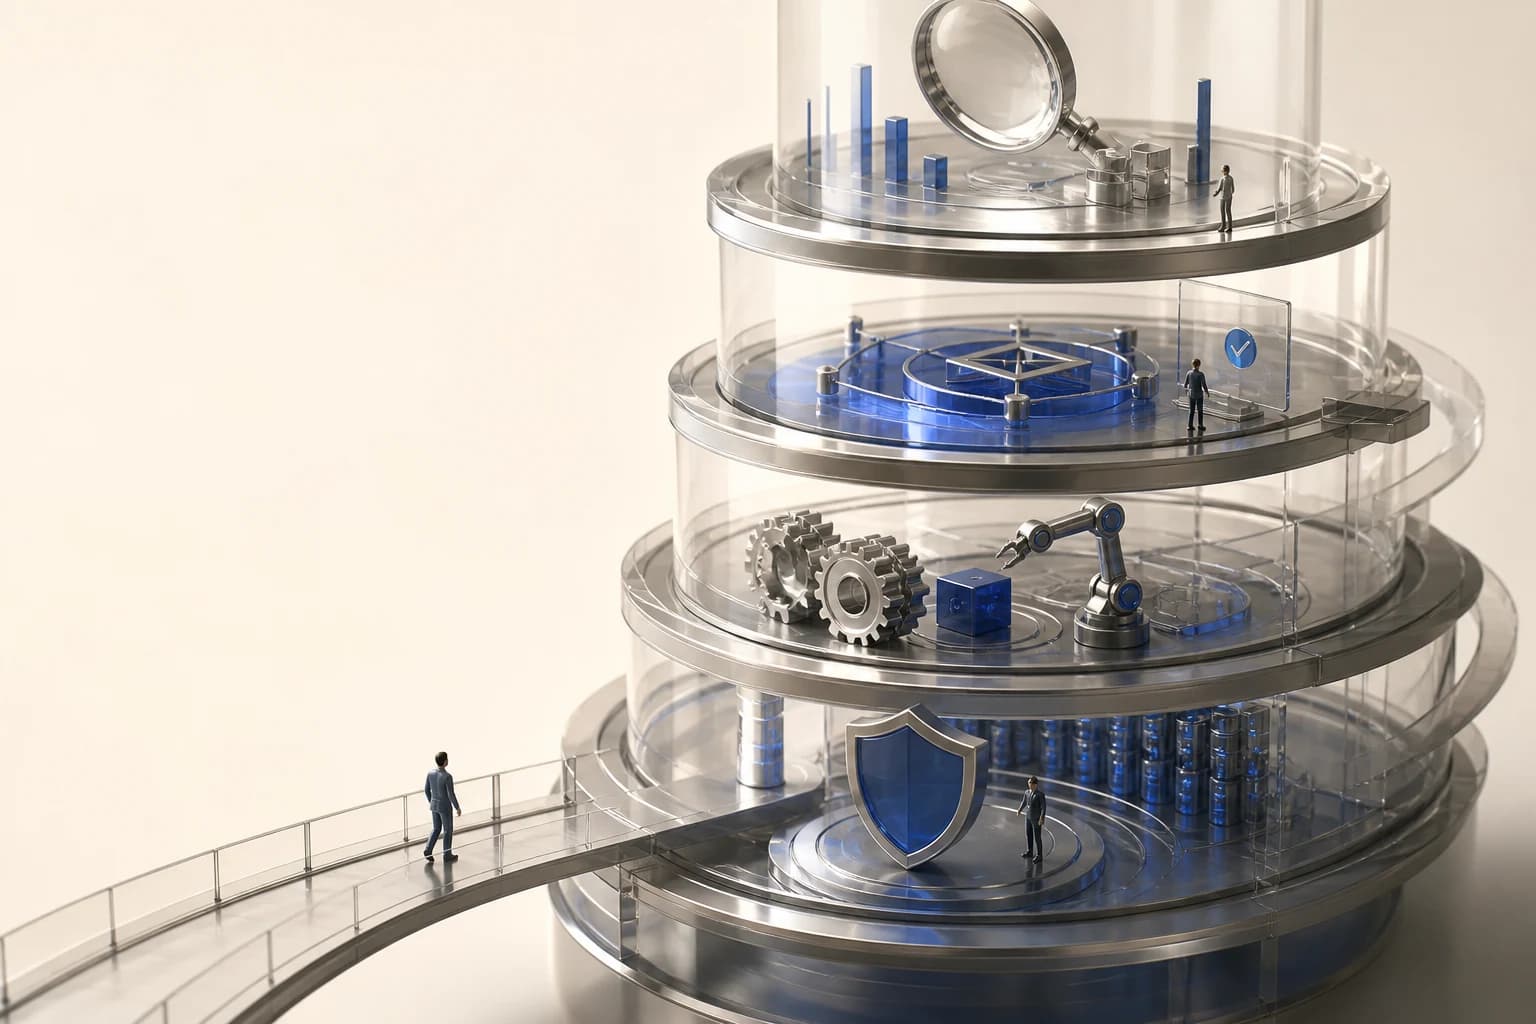
There is no single correct answer, but there are criteria we can design: autonomy layers. Instead of lumping work into one automation, divide it into observation, recommendation, execution, and external action. Each layer can have different owners, approval methods, rollback procedures, and log-retention periods. The principle is simple. Even the same agent should not always operate with the same authority. Permissions should be allocated by the impact of the task, not the model’s ability.
1. Separating autonomy layers turns team anxiety into operating criteria
Four layers are commonly used in practice. First, the observation layer: the agent only reads and summarizes, never changing state. Second, the recommendation layer: it proposes options and priorities but does not execute without human approval. Third, the limited-execution layer: it automatically performs only reversible actions in internal systems. Fourth, the external-action layer: actions directly affecting customers, the public, or spending must have multiple approvals or a delayed queue.
Many teams fail because they skip these stages, crossing boundaries on the intuition that a task looks safe. Intuition is fast but not reproducible. Operating criteria become tied to individual instincts, producing confusion where something passes today and is blocked tomorrow. Documented layer definitions allow new team members to reach the same judgment. Automation quality begins with consistency in team decisions, not model parameters.
 Conceptual diagram of autonomy layersView original
An important secondary axis is reversibility: can the action be undone? Tag cleanup, temporary queue sorting, and internal document drafts are highly reversible. Payments, public publication, deletion of personal information, and external announcements are much less so. Lower reversibility calls for more approvals and stronger pre-execution verification. This principle alone can prevent half of incidents in advance.
2. Write recovery time before permissions in an operator agreement
Permission matrices are common in the field; recovery-time agreements are not. This is precisely where problems grow. Automation costs more after failure than at execution. The agreement’s first line should therefore ask not what the agent can do, but how quickly normal conditions can be restored after something breaks.
At minimum, an operator agreement should include the following.
- Scope: Specify the data an agent may read, systems it may write to, and tools it may call.
- Execution conditions: Define the signals required to execute and the conditions that prohibit execution.
- Verification stages: Establish automatic checks for format, policy violations, prohibited terms, external links, and other issues, plus triggers for human review.
- Rollback procedure: Fix in a playbook who restores what, in which order, and within how many minutes.
- Audit logs: Retain inputs, decision rationale, tool calls, and final results in a traceable form.
These five lines change the team’s conversation. Instead of “Is this model okay?”, it becomes “This task is layer 3; can we meet a twenty-minute recovery SLA?” When emotional debate moves to operational metrics, automation finally becomes an organizational asset.
 Operator agreement checklistView original
Delayed Publish is especially powerful in the external-action layer. Rather than releasing output immediately, hold it in a queue for 5–15 minutes. Automatic verification runs again during that interval, and a person can stop it if needed. This buffer of a few minutes greatly reduces brand risk. It may appear slightly slower, but preventing one major incident has a much greater effect.
3. Trust in agents depends on explainability, not answer accuracy
Teams fear automation less because it can be wrong than because they may not know why something happened. Trust design therefore cannot rely on accuracy alone. Explainability is essential. Even for the same result, teams must be able to replay which inputs supported it, which policies it passed, and which tools it called.
Practical ways to improve explainability are simpler than expected. Keep three things for every execution. First, a sentence explaining the choice: a written policy rationale such as “This request affects external parties, so it was routed for approval.” Second, alternative candidates: summarize why other routes were not selected. Third, the stop-button location: specify where a person can intervene. These records fuel the next rule improvement as well as incident investigation.
Operationally mature teams examine successful-stop rates alongside accuracy reports. Organizations that can stop automation well ultimately keep it running longer. Stopping is a skill of control, not slowness. Only with control can greater autonomy be allowed.
 Flowchart of explainability logsView original
The essence of automation is simple: it is not handing work to a model, but designing the boundaries of decision-making authority and assigning responsibility. Autonomy layers may look like technical documentation, but they are closer to a document of organizational culture: a contract recording who accepts risk, who approves, and how failure becomes learning.
Teams that achieve results in the agent era do not merely seek smarter models. They first create clearer agreements and expand automation only on that foundation. Speed follows. Lasting systems always follow the same order: establish boundaries, allocate authority, and accelerate last.