Agents do not become intelligent by remembering more. They work reliably only when they can retrieve the context needed now briefly and accurately.
One of the first misconceptions teams encounter when building agent systems is the expectation that retaining conversations longer, accumulating logs, and connecting a vector database will automatically make the system smarter. In production, retrieval quality rather than storage volume determines performance. However much data is accumulated, lengthy past context unrelated to the current request can destabilize the model. Answers become verbose, priorities blur, and unwarranted confidence grows. The question is ultimately not whether memory exists, but how it is divided into layers and by what criteria it is recalled.
People are similar. We do not recall everything at once. A screen just seen, today’s schedule, old habits, and important principles surface differently. Agents likewise should treat fresh user input as immediate working memory, compress the current session’s accumulated context into short-term memory, and separate policies, preferences, and domain knowledge as relatively stable long-term memory. Without these layers, the system overworks itself by carrying everything on every request.
1. Memory layers separate decision timelines, not just storage locations
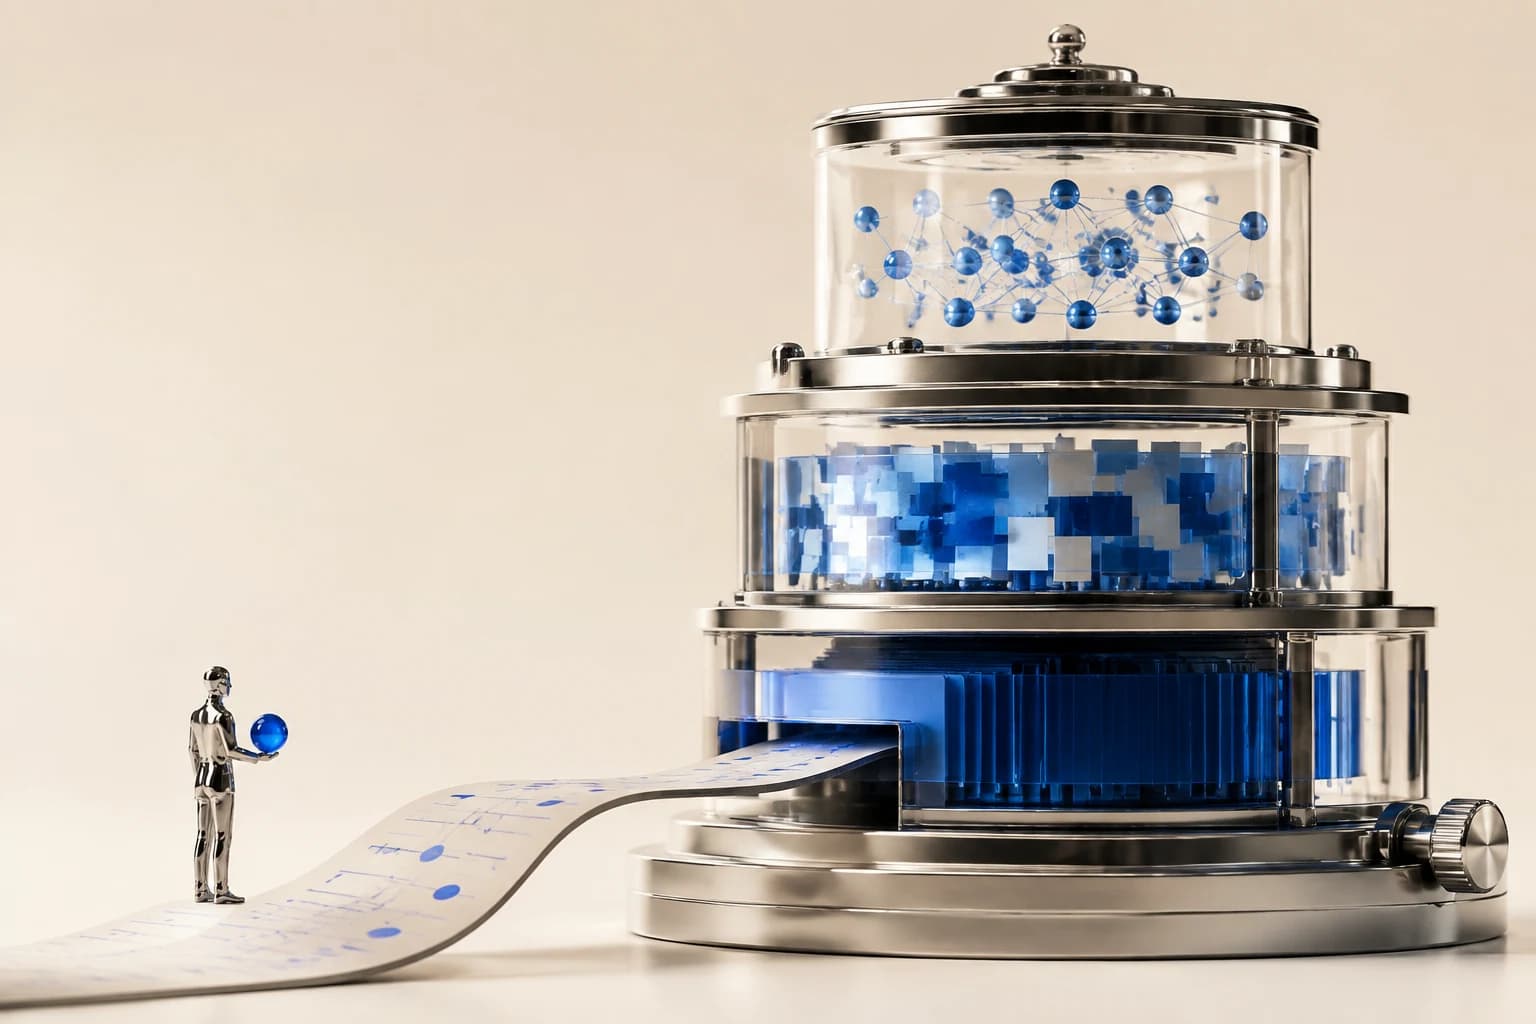
A useful starting point is three layers. The first is working memory: short-lived, high-priority data required for the current turn, such as user input, tool results, and the rationale for the immediately preceding decision. The second is session memory: context valid for minutes or hours, including agreed goals, constraints, failure history, and summaries of intermediate outputs in this conversation or execution. The third is long-term memory: information reused across requests, such as user preferences, recurring operating rules, frequently referenced playbooks, and verified domain knowledge.
Do not make this division by storage technology. Some teams think in tool names: SQL or vector databases mean long-term memory, Redis means short-term. Real design should proceed in reverse. First define how long the information remains valid, which decisions it supports, and the cost of being wrong. “The user prefers concise answers” is a candidate for long-term memory, while “use bullets instead of a table for this request” belongs closer to session memory. Mixing them can erase lasting principles or harden a temporary request into a permanent habit.
The essence of memory layers is time, not location. Some information should be discarded after thirty seconds; some must survive until the next run; some must not be promoted before human review. Separating these timelines shortens prompts, clarifies retrieval criteria, and reduces the spread of incorrect memories through the system.
 Agent memory layers, image 1View original
2. Good retrieval means narrowing without error, not finding more
The most common failure in retrieval-based memory is attaching many related documents. Seeking greater recall, teams feed the top ten, twenty, or even thirty chunks into a model. It appears to reduce missed information, but response quality often falls. More context does not simply make a model smarter; it makes it process more competing signals. Similar but subtly different historical instructions can cause excessive trust in old patterns over the current request.
To improve retrieval quality, examine post-processing compression as well as retriever accuracy. Search only gathers candidates; actual operating quality comes from reducing them to a few short decision inputs. If long-term retrieval returns six items, do not attach them unchanged. Resummarize them into directly usable statements: “The user likes technical explanations, but answers should be brief,” “Confirm before external delivery,” and “The recent project is DMS automation.” What the agent reads should resemble decision statements more than original documents.
Retrieval also needs exclusion conditions. Personal information irrelevant to the request, outdated conclusions, revoked policies, and experiments shown to have failed must be excluded even if retrieved. A memory system should filter what must not be recalled now, rather than merely remember more. Teams reducing incidents in practice refine filters even more persistently than retrievers.
Three criteria help: does this directly affect the current goal? Has a person verified it? Does freshness matter? It is better to decisively exclude memories that do not pass these questions. An agent’s context window resembles an operating table more than a warehouse. Lay out only the necessary instruments to keep hands from getting tangled.
 Agent memory layers, image 2View original
3. Mature memory systems need approval and promotion rules for writing memories too
Many designs invest in retrieval but are casual about what gets remembered. If user statements, model-inferred tendencies, and one-off results are stored without distinction, long-term memory becomes contaminated. In systems where an agent both summarizes and saves for itself, small misunderstandings can harden into habits through repeated runs. “This user always wants long reports” is a typical incorrect generalization. Initially minor, it eventually skews the system’s tone and priorities.
Memory writing therefore needs minimum promotion rules. Information arising during work should first remain only in session memory; only repeated or explicitly confirmed facts become candidates for long-term memory. Operating rules are no different. Immediately storing a temporary workaround for one incident as a lasting policy can obstruct the next run. Long-term memory must be a repository of verified agreements, not convenient storage.
Clearly defining human-review points greatly improves quality. High-consequence information—user preferences, external communication rules, security restrictions, and conditions for automation involving money—is safer with confirmation than automatic promotion. Low-risk items such as recurring formatting preferences or document-structure rules may be promoted automatically. The key is not making all memories permanent at the same speed.
Memory must also be observable operationally. Track how often each memory is retrieved, whether it helps actual responses, and the proportion corrected by people. Only then can accumulated data be distinguished as an asset or noise. A system that does not measure memory quality is more likely to accumulate old self-confidence than to grow smarter over time.
Finally, memory design directly affects user experience. An agent recalling necessary context accurately seems to understand me; one raising unnecessary history leaves the discomfort of being over-recorded. A good memory system therefore aims not to know a lot, but to know only what is needed at the appropriate moment, with a structure that can quickly forget and correct mistakes. Memory in the agent era is closer to trust design than storage technology, because retrieval quality is relationship quality.
 Agent memory layers, image 3View original