AI-enabled services tend to fail in similar ways. Early releases win applause for generation quality; once traffic arrives, latency and cost spiral together. Teams spend late nights swapping models and shortening prompts, only to face the same problem the following week. The underlying issue is not one model, but the absence of routing policy.
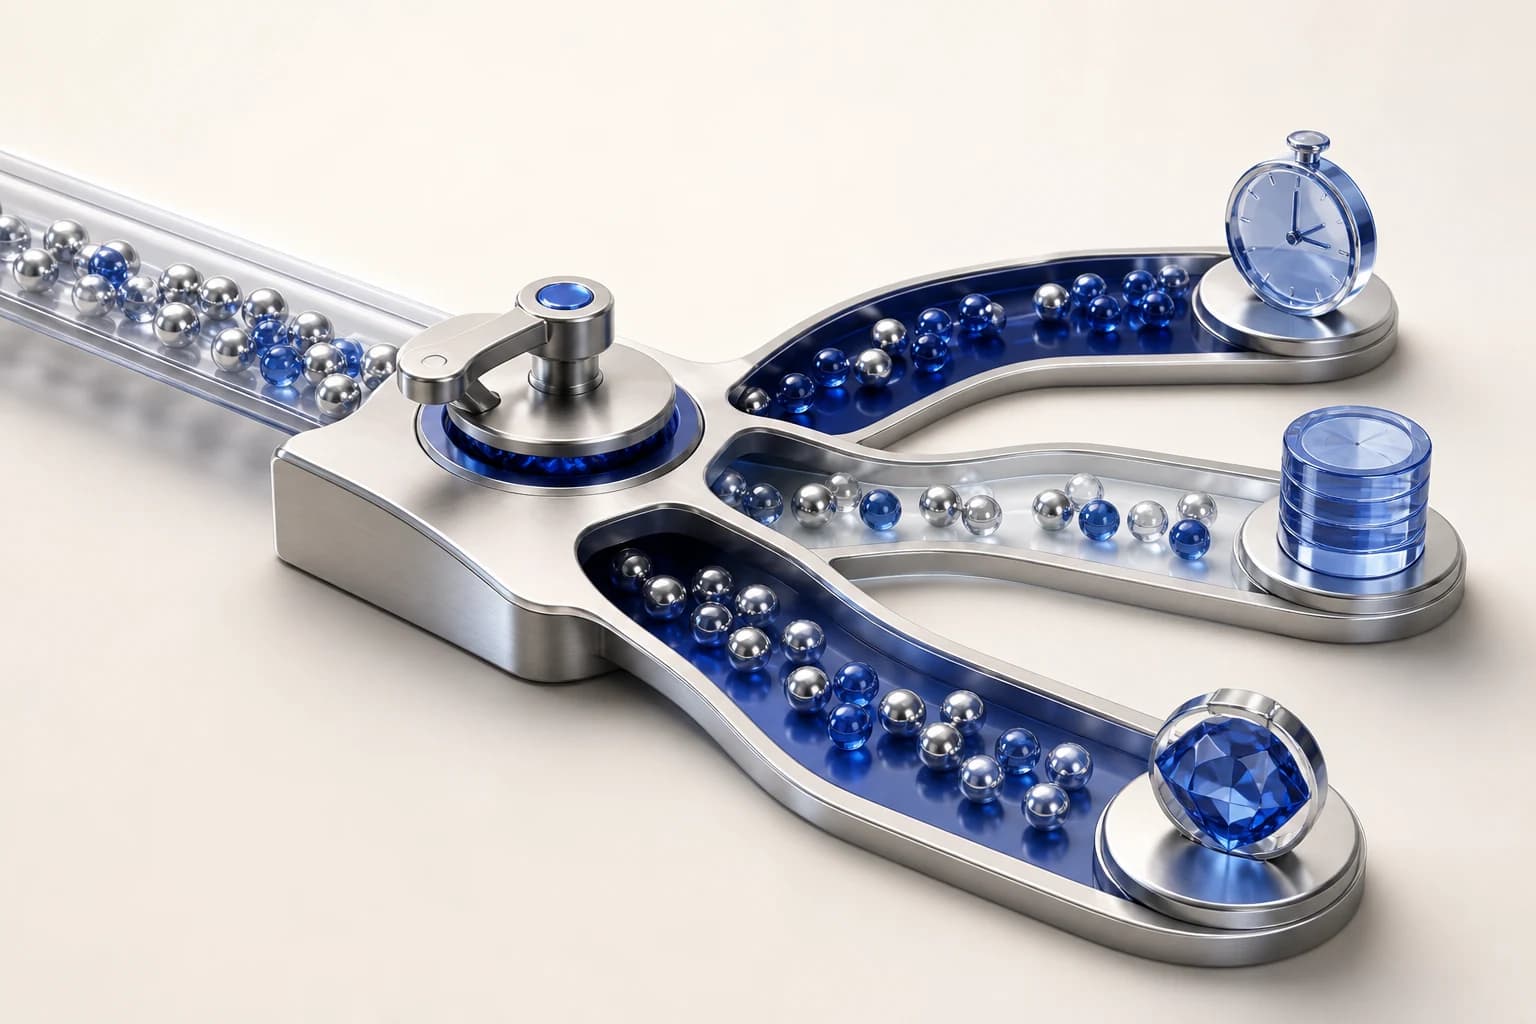
Small teams do not need to classify every request with a major platform’s precision. Simply establishing at least three paths according to the character of a request transforms operations: real-time requests requiring immediate responses, cost-sensitive bulk requests, and high-value requests prioritizing quality. Without these divisions, long inputs and expensive inference mix with real-time traffic, raising overall latency and ultimately breaking the user experience that matters most.
1. Abandon identical treatment for every request and declare routing criteria first
Many teams postpone routing until after implementation. In actual operations, however, criteria must be decided before code. Without written rules specifying which requests go down which paths, team members add and remove ad hoc conditions until policy collapses. Routing criteria need not be complicated. These four signals, for example, can suffice.
- Input token length: short, medium, or long
- User tier: free, paid, or enterprise
- Acceptable response delay: real-time or several minutes
- Task type: summarization/classification, generation/planning, or analysis/reasoning
The purpose is predictable resource usage, not perfect classification. The key structure quickly sends 95% of requests to a stable path while isolating expensive exceptions into a controlled high-performance path. Operations a small team can handle always emerge from reducing exceptions.
 Latency-aware routing mapView original
An often-missed point is that routing is not a ruleset fixed once and forgotten. It is closer to a contract readjusted as a product grows. Strong restrictions on long inputs from free users may be necessary early on, while high-value workflows should gain more room after paid conversion stabilizes. Routing policy should therefore be an operating document under version control, not merely a code comment. Record when criteria changed, why, and what changed so the next incident can be traced.
2. Divide token budgets by request lifecycle, not feature
The first move teams make to reduce cost is shortening output. That has an immediate effect, of course. But larger leaks occur in inputs, retries, and post-processing chains. Token budgets should therefore be designed around the request lifecycle rather than individual features.
A useful method divides each request into four budget buckets.
- Input preparation: Condense source text, remove duplicates, and cut unnecessary context.
- Primary generation: Generate the default model response.
- Retry/recovery: Run alternative paths after timeouts or filter blocks.
- Post-processing: Align formatting, check safety, and produce summaries.
This makes it possible to trace today’s cost spike by stage instead of feature name. If generation cost is stable but retry cost surges, suspect network latency or timeout settings before model performance. If input-preparation cost rises sharply, quickly investigate changed upload formats, a new client release, or broken external-integration formats.
 Token budget dashboardView original
It is also important to set both a per-request ceiling and a time-window ceiling. A per-request limit alone lets cumulative costs explode under heavy traffic; a time-window limit alone lets a few costly requests consume the resources needed for core user experience. A practical dual defense uses different limits by user tier plus a separate service-wide cost boundary, such as a total budget per ten minutes. For small teams, clear ceilings produce stability more than sophistication does.
3. During incidents, simplify paths before replacing models
When an incident strikes at night, the instinct is to cover the problem with a stronger model and larger context. The first response that actually saves the service goes the other way: reduce paths, simplify processing, and quickly converge on a stable range. Prepare a short failover protocol in advance.
The following five stages are one example.
- Detect: Identify spikes in P95 latency, retry rates, and error codes.
- Throttle: Restrict low-priority traffic and temporarily limit long inputs.
- Reroute: Reduce costly paths and divert traffic to lower-latency models.
- Stabilize: Extend cache TTL and simplify post-processing.
- Recover: Gradually restore policy after traffic normalizes.
The key is giving up the desire to restore complete normality at once. Protect core functions first and place the remainder in temporary modes to stop the outage users experience. Especially in subscription products, ten minutes of predictable performance causes far less churn than hours of slow recovery.
 Failover protocol boardView original
Recovery must include a recording format. Without recording the conditions that triggered throttling and the metrics used to restore normal policy, the next incident will again be handled by instinct. A small team’s advantage is repeatable operational memory, not headcount. Accumulating failover logs transforms a team that changes models in panic into one that adjusts paths on evidence.
4. A minimum operating checklist to apply by next quarter
There is no need to copy global technology companies’ operations wholesale. Small teams need a minimum checklist they can apply today. Fix these four elements and resilience rises quickly when latency and cost become unstable together.
- One-page routing criteria: input length, user tier, delay tolerance, and task type
- Request-lifecycle budget table: ceilings for input, generation, retries, and post-processing
- Five-stage failover card: detect → throttle → reroute → stabilize → restore
- Incident-review template: change time, affected scope, restoration conditions, and recurrence prevention
The essence of AI operations is ultimately predictable system behavior, not an astonishing demo. Users value a service that remains broadly stable whenever they use it more than one offering occasionally brilliant answers. Model innovation will keep accelerating, but operating principles grow stronger as they become simpler. What is needed is not a showier stack, but the fundamentals of dividing paths, honoring budgets, and repeatedly recovering. Those fundamentals are an advantage small teams can secure first.