Today, AI product-team failures rarely begin with model performance. They usually begin with missing signals behind questions like "Why is it so slow only today?" or "Why does it fail strangely for this particular customer?" The smaller the team, the more it needs a structure that catches anomalies quickly with limited instrumentation instead of imitating a giant platform.
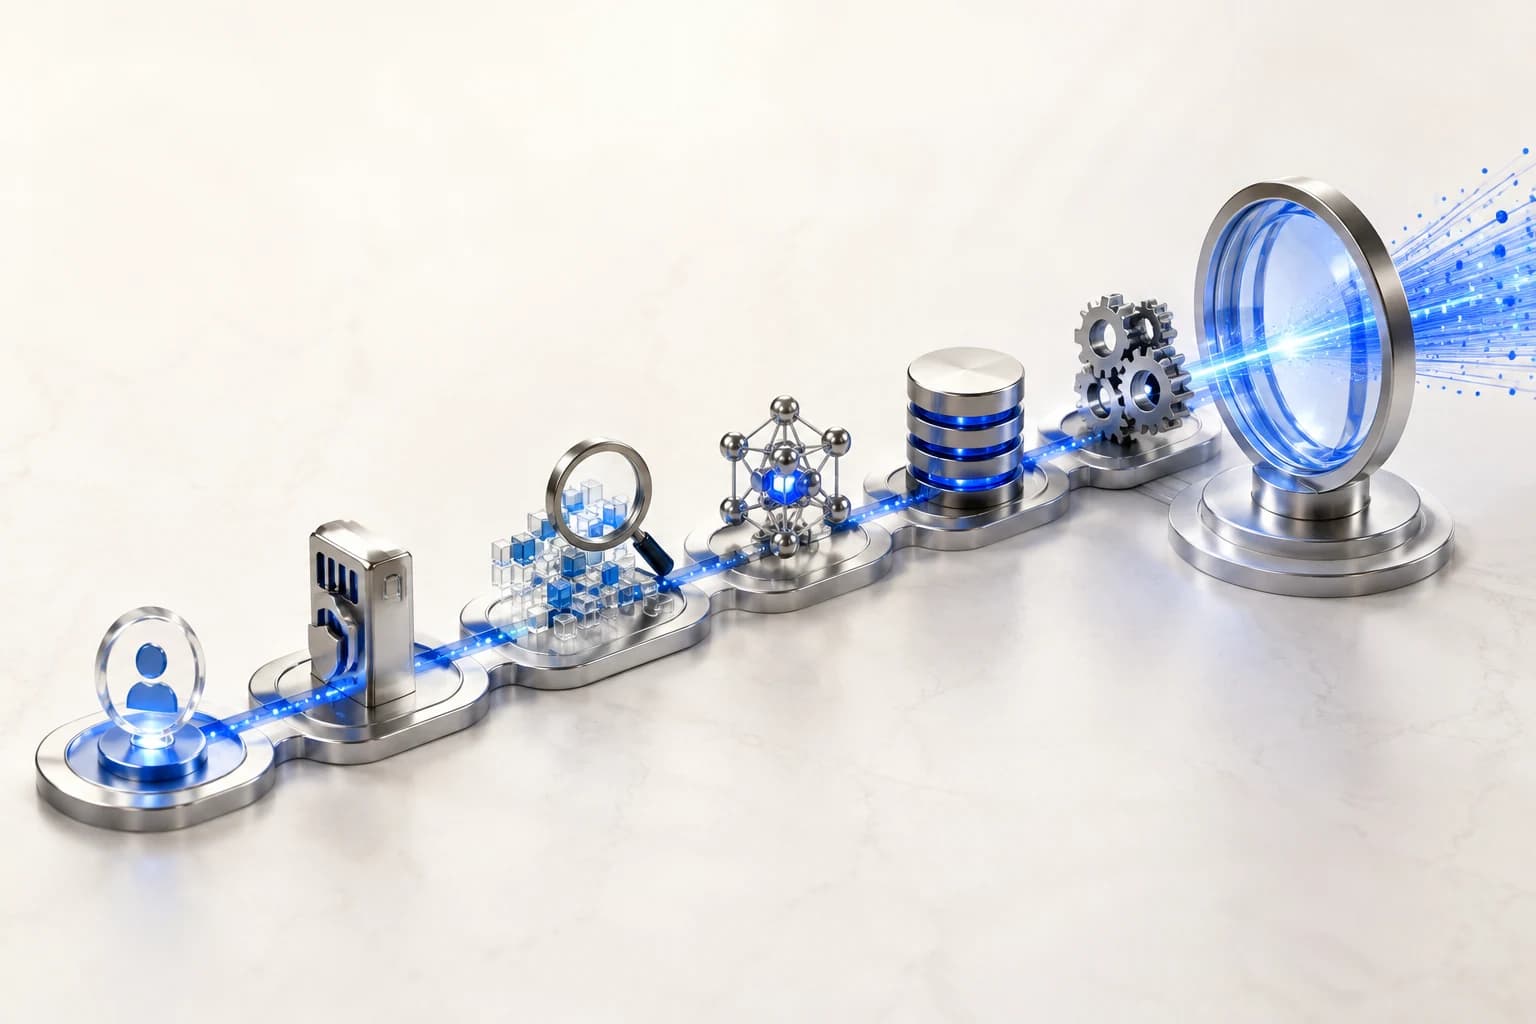
Most teams fall into the same early trap: believing that an attractive dashboard will stabilize operations. Incident response works the other way around. During an incident, the first need is not dozens of graphs but a signal system that immediately exposes a clue to the current bottleneck. LLM features intertwine input length, model routing, cache hits, external API latency and post-processing, so a single metric such as average response time explains very little. Small teams cannot observe every stage perfectly like large companies. Their strategy must differ. Rather than trying to see everything from the beginning, it is more realistic to establish five signal axes directly tied to product survival, then expand gradually.
1. Establish a Minimal Identifier for Tracing Each Request
Observability begins with connectedness, not log volume. Unless one request can be tied to the same ID from the user’s question through the final response, other metrics are nearly decorative. Propagating a request_id through frontend events, the gateway, model calls, vector search, post-processing and storage lets you distinguish retrieval, generation and rendering problems within minutes. Perfect distributed tracing is not the point. For a small team, standardizing JSON log fields alone makes a large difference. Align request_id, user_tier, model, input_tokens, output_tokens, latency_ms and error_code as common fields, and establish a rule blocking deployment if this schema breaks.
 AI runtime signal stack overviewView original
One of the most frequent operational failures is inconsistent field names rendering alert conditions ineffective. If one service uses latency, another duration and another response_time, an alarm may sound in the middle of the night while root-cause tracing still requires manual grep. For a small team, that time loss is critical. Schema agreement looks tedious, but is among the investments that cut operating costs most.
2. View Quality, Cost and Speed Together, but Keep Alerts Simple
AI operations fluctuate along three axes together. Higher answer quality can spike costs; restricting costs can slow responses; meeting speed targets can increase quality variation. Dashboards must show the three together. Overlay hourly success rates, P95 latency, average cost per request, retry rates and safety-filter block rates on one screen, for example, and you can quickly see whether today’s cost rise came from a model change or a retry surge. Alerts, by contrast, fail when complex. At most, four alert policies are enough for a small team.
First, a sharp drop in success rate. Second, a spike in P95 latency. Third, a spike in cost per request. Fourth, consecutive occurrences of a specific error_code. Most other metrics belong in reports. More alarms dull people’s sensitivity until they miss genuine incidents. The goal is detecting user-visible failures first, rather than detecting every anomaly.
 Three-axis ops monitor without human figureView original
One more point: an alert that provides only a number is not useful. Include the latest deployment commit hash, affected model, leading error codes and traffic change over the last 10 minutes to speed response. A small team’s operational maturity is determined not by tool names but by how clearly one alert directs a person’s next action.
3. Write Recovery Playbooks in Advance to Halve Nighttime Incidents
However good observability is, without a recovery sequence the sleepless nights repeat. Small teams need a 10-minute recovery playbook, not a huge runbook. For example, for model latency spikes: temporarily reduce the proportion of expensive-model calls → extend cache TTL → check background queue length → shorten external search timeouts. For cost spikes: enable long-input truncation → batch lower-priority user requests → limit generation length for nonessential features. For quality drops: roll back to the previous stable prompt → restore retrieval’s top-K value → review resetting safety-filter thresholds. Documenting these sequences lets whoever is responsible respond consistently.
 Recovery playbook flowchart with abstract nodesView original
The key is consistency of judgment, not the percentage automated. A playbook should clearly mark what runs automatically and where human approval begins, rather than demand unconditional automatic execution. It is safer to retain human approval for hard-to-reverse actions such as payments and external sending. Reversible measures, such as cache-policy adjustments or circuit-breaker switching, can be automated. Small teams become strong through repeatable recovery decisions, rather than massive infrastructure.
AI runtime operations are ultimately decided by how quickly problems are detected and how consistently recovery happens, rather than dazzling model demos. The minimum you can do today is straightforward: standardized request identifiers, four essential alerts and a 10-minute recovery playbook. Establishing these three can move a team from noticing anomalies late and accumulating losses to detecting them early and limiting harm. A small team needs observability for survival, not perfect observability.